Need help? Contact our experts

973-362-9986
Data Engineering Services

In today’s data-driven world, organizations need reliable, scalable, and well-architected data platforms to turn growing volumes of information into meaningful business insights. Our Data Engineering services help businesses design, build, modernize, and manage end-to-end data solutions that transform raw data into trusted, analytics-ready information.

By leveraging modern cloud platforms and technologies such as Microsoft Azure, Microsoft Fabric, Databricks, AWS, SQL, Python, Spark, Lakehouse architectures, and ETL/ELT frameworks, we help organizations integrate data from multiple sources, automate data pipelines, improve data quality, and create scalable platforms for analytics, reporting, AI, and machine learning.

Whether you're modernizing legacy systems, building a new enterprise data platform, implementing a Data Lakehouse, or developing real-time data pipelines, our Data Engineering solutions provide the scalability, security, governance, and reliability needed to maximize the value of your data.

Core Capabilities

Scalable Data Architecture

We design modern and scalable data architectures that support structured, semi-structured, and unstructured data across cloud, hybrid, and enterprise environments. Our solutions include Data Lakes, Data Warehouses, Lakehouses, Medallion Architecture, and real-time data platforms.

Data Integration & ETL/ELT

We build automated ETL and ELT pipelines to ingest, transform, validate, and integrate data from databases, APIs, applications, files, streaming platforms, IoT devices, and third-party systems. Using Azure Data Factory, Fabric Data Factory, Databricks, Apache Spark, AWS Glue, SQL, and Python, we deliver trusted data on demand.

Data Processing & Transformation

Our data engineering solutions transform raw information into clean, standardized, and analytics-ready datasets. We implement business rules, data cleansing, schema validation, deduplication, aggregation, enrichment, and transformation processes to improve data accuracy and usability.

Assessment & Data Strategy

We assess your existing data environment, applications, infrastructure, data sources, integration processes, and business requirements. Based on our findings, we develop a customized data architecture and modernization strategy aligned with your business and technology goals.

Data Quality, Governance & Security

We incorporate data quality, governance, security, lineage, metadata management, access controls, and monitoring throughout the data lifecycle. This helps organizations maintain reliable, secure, compliant, and trusted enterprise data.

Monitoring, Optimization & Support

We continuously monitor data pipelines and platforms to identify failures, performance bottlenecks, and data-quality issues. Through automated monitoring, alerting, orchestration, and performance optimization, we help maintain reliable data environments.

Data Pipeline & Platform Implementation

Our team designs and implements end-to-end data pipelines covering every stage of the enterprise data lifecycle for both batch and real-time/streaming processing:

End-to-End Pipeline Architecture:

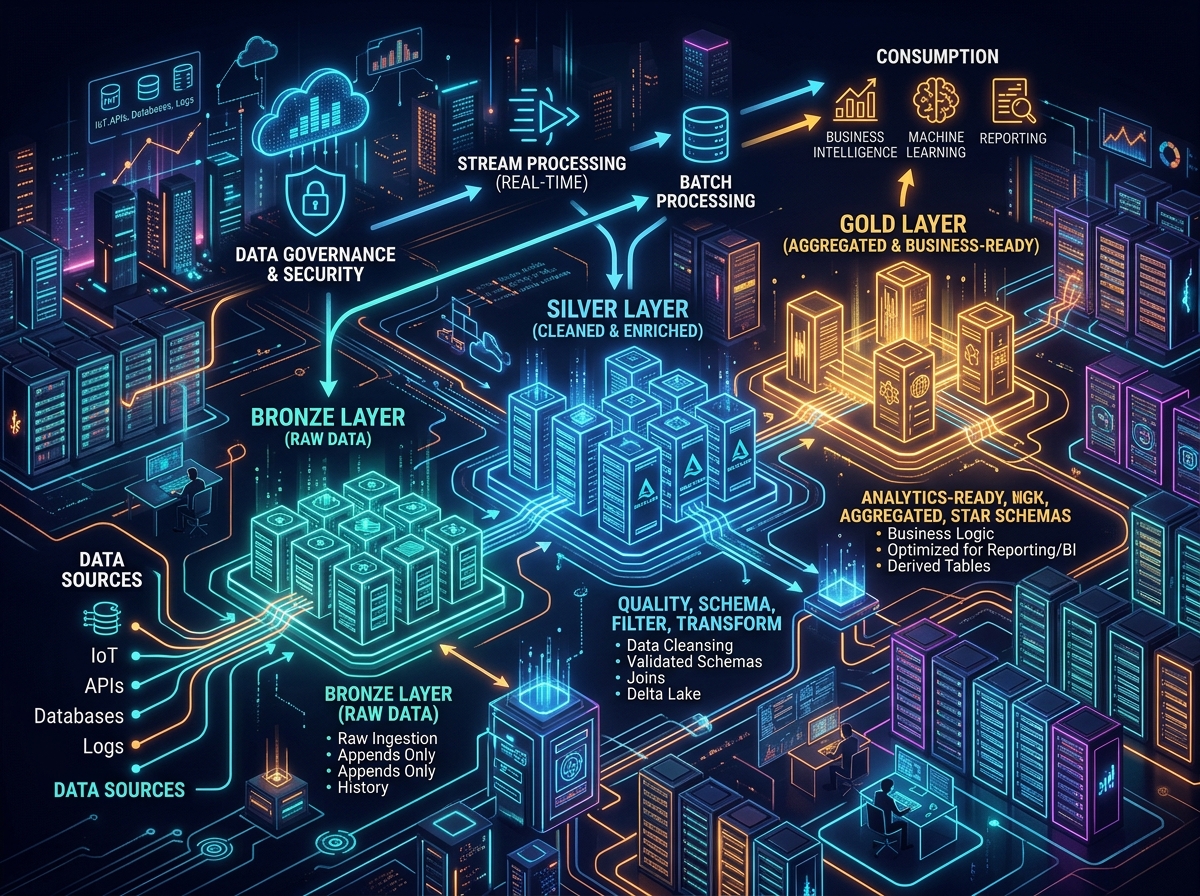
Data Sources → Ingestion → Raw / Bronze Layer → Transformation → Silver Layer → Business / Gold Layer → Data Warehouse / Lakehouse → Analytics, BI, AI & Machine Learning

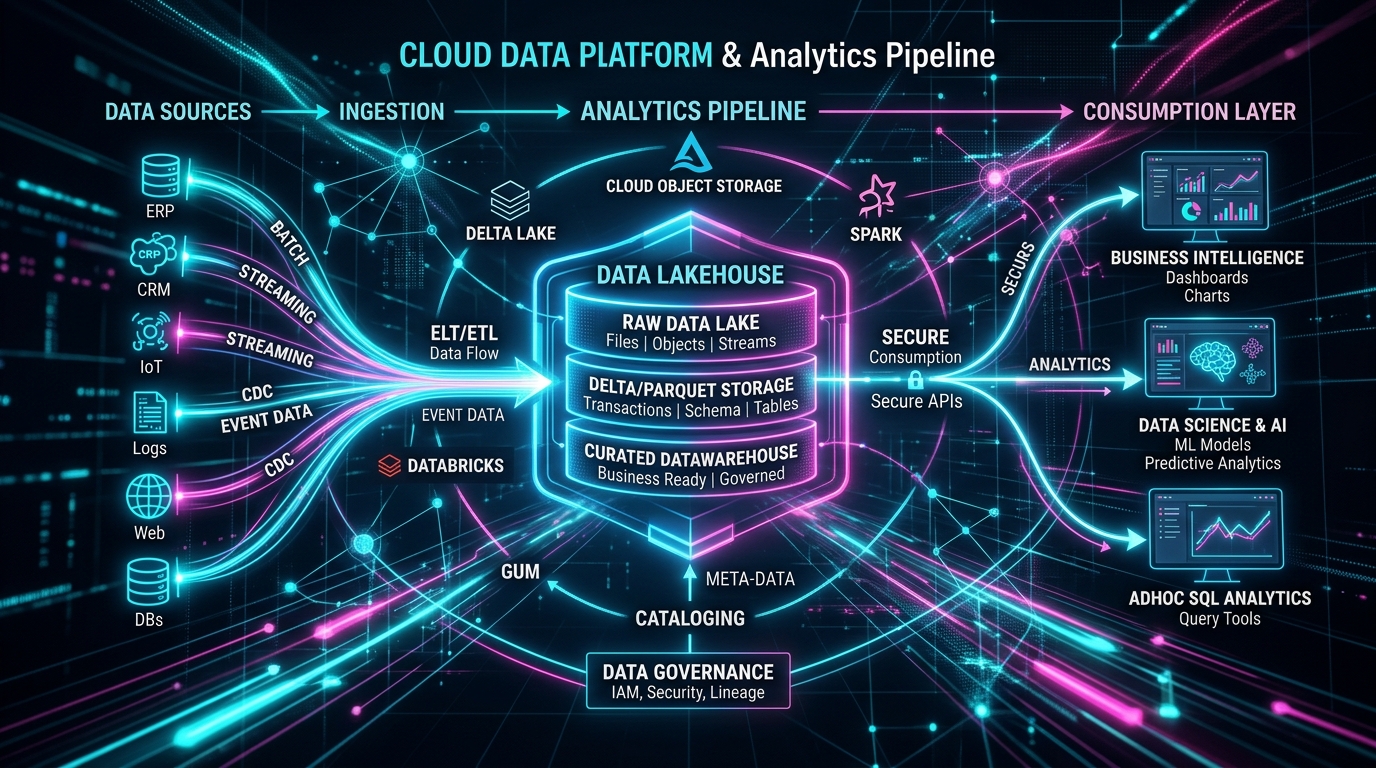
Our Data Engineering Technology Stack

Cloud Platforms: Microsoft Azure, Amazon Web Services (AWS), Google Cloud Platform (GCP)
Modern Data Platforms: Microsoft Fabric, Azure Databricks, AWS Databricks, Databricks Lakehouse Platform, Snowflake
Data Integration & Orchestration: Azure Data Factory, Microsoft Fabric Data Factory, AWS Glue, Google Cloud Dataflow, Databricks Workflows, Snowflake Snowpipe, APIs
Data Processing & Engineering: Apache Spark, PySpark, Python, SQL, Databricks, Delta Lake
Data Storage: Azure Data Lake Storage Gen2 (ADLS), Microsoft OneLake, Amazon S3, Google Cloud Storage, Delta Lake
Data Warehousing: Microsoft Fabric Warehouse, Snowflake, Azure Synapse Analytics, Amazon Redshift, Google BigQuery, Databricks SQL Warehouse
Databases: SQL Server, Azure SQL, PostgreSQL, MySQL, Snowflake
Real-Time & Streaming: Apache Kafka, Azure Event Hubs, AWS Kinesis, Google Pub/Sub, Databricks Structured Streaming
Analytics & Business Intelligence: Microsoft Power BI, Fabric Analytics, Databricks SQL, Snowflake, Google BigQuery
AI & Machine Learning: Azure Machine Learning, Databricks MLflow, Microsoft Fabric Data Science, AWS SageMaker, Google Vertex AI, Snowflake Cortex AI
DevOps & CI/CD: Azure DevOps, GitHub, Git, CI/CD, Infrastructure as Code (IaC)
Data Governance & Security: Microsoft Purview, Databricks Unity Catalog, Snowflake Governance, RBAC, data lineage, encryption, auditing, and access management

Our Data Engineering Process

A proven, structured 7-step methodology to design, build, govern, and continuously optimize your enterprise data infrastructure.

Data Engineering Process Diagram
01 Phase 1

Assess & Discover

Understand business objectives, existing systems, data sources, challenges, security requirements, and analytics needs.

02 Phase 2

Architect & Design

Develop target architecture, data models, ingestion strategy, storage layers, transformation framework, governance model, and technology roadmap.

03 Phase 3

Ingest & Integrate

Connect enterprise data sources and build automated batch or real-time ingestion pipelines.

04 Phase 4

Transform & Validate

Clean, standardize, enrich, validate, and transform data into trusted datasets using scalable processing frameworks.

05 Phase 5

Store & Serve

Organize data within Data Lakes, Lakehouses, and Warehouses and make curated datasets available for analytics, reporting, applications, AI, and machine learning.

06 Phase 6

Govern & Secure

Implement security, access controls, data quality, metadata, lineage, auditing, and governance policies.

07 Continuous Optimization

Monitor & Optimize

Continuously monitor pipelines, improve performance, control cloud costs, automate deployments, and scale the platform as business requirements evolve.

With our Data Engineering services, organizations can establish a trusted data foundation that transforms fragmented information into secure, scalable, and actionable data—empowering better analytics, faster decision-making, and advanced AI capabilities.